DATA CATALOG
A verifiable catalog of multimodal language data
Nine datasets span speech, video, text, eye tracking, physiological signals, motion capture and multimodal fusion. Every dataset passes sync, content, agreement and reproducibility verification before it is licensed for research or product use.
Delivery standard
- Verified multimodal corpus
- 12,400hours
- Median annotator agreement
- 0.91κ
- Batch QA pass rate
- 98.7%
Sync measurement, content spot checks and double-blind agreement review are completed before delivery, with a reproducibility audit checklist included.
- Datasets
- 9
- Modalities
- 7
- Languages & dialects
- 38 languages
- Median sync error
- 1.4 ms
01 / Modality landscape
Seven modalities on one shared timeline
Assets are organized by modality but intersect on the same time base. Choose a modality to jump straight to matching datasets, or open the catalog to see every entry.
Speech & paralanguage
Read speech, interviews and natural conversation with phoneme-level alignment, prosodic and paralinguistic annotation.
Filter this modalityVideo & visual behaviour
Lip movement, facial expression and real-world scenes, frame-synchronized with audio and ready for behaviour coding.
Filter this modalityText & annotated corpora
Verbatim transcripts, annotated text and experimental stimuli with word boundaries and syntactic information.
Filter this modalityEye tracking & visual attention
Fixations, saccades and pupil data that reconstruct the time course of reading and visual attention.
Filter this modalityPhysiology & neural signals
EEG, electrodermal activity, heart rate and respiration, aligned to stimulus events at millisecond precision.
Filter this modalityMotion & posture
Gesture, posture and joint trajectories captured in teaching and interaction scenarios.
Filter this modalityMultimodal fusion
Multi-channel fused delivery and cross-modal alignment for fusion modelling and system evaluation.
Filter this modalityCounts reflect the datasets currently listed; multimodal datasets are counted under each modality they cover.
02 / Catalog
Nine datasets, combinable around a research question
Each dataset can be licensed on its own or combined by scenario, speaker and annotation layer into a custom subset. Use the filters to narrow the catalog by modality.
Showing 9 datasets
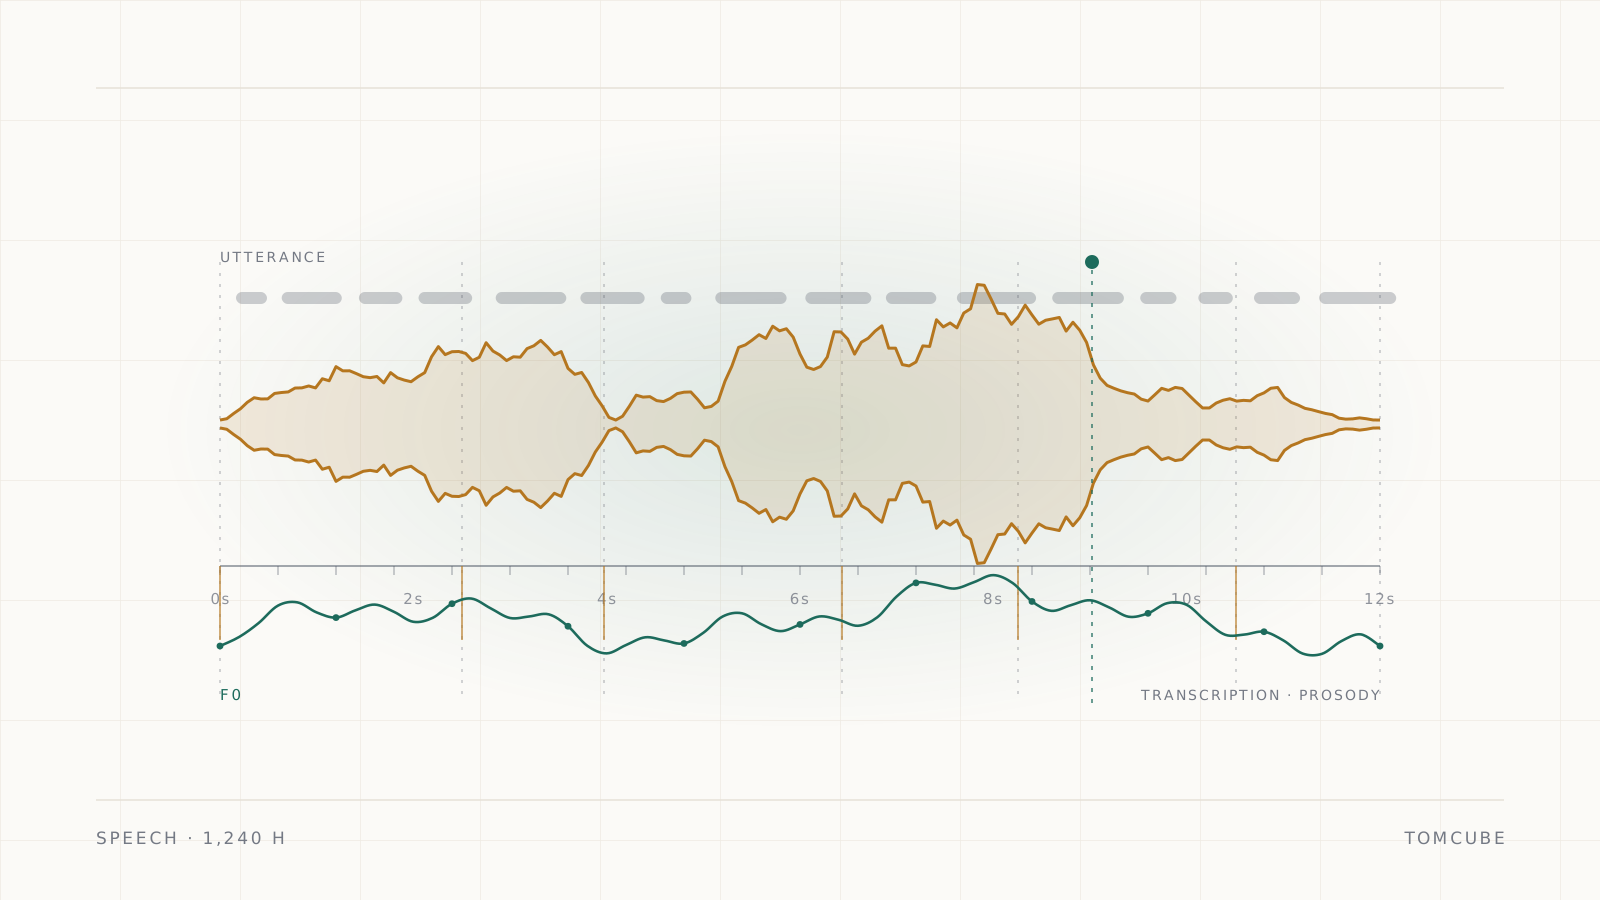
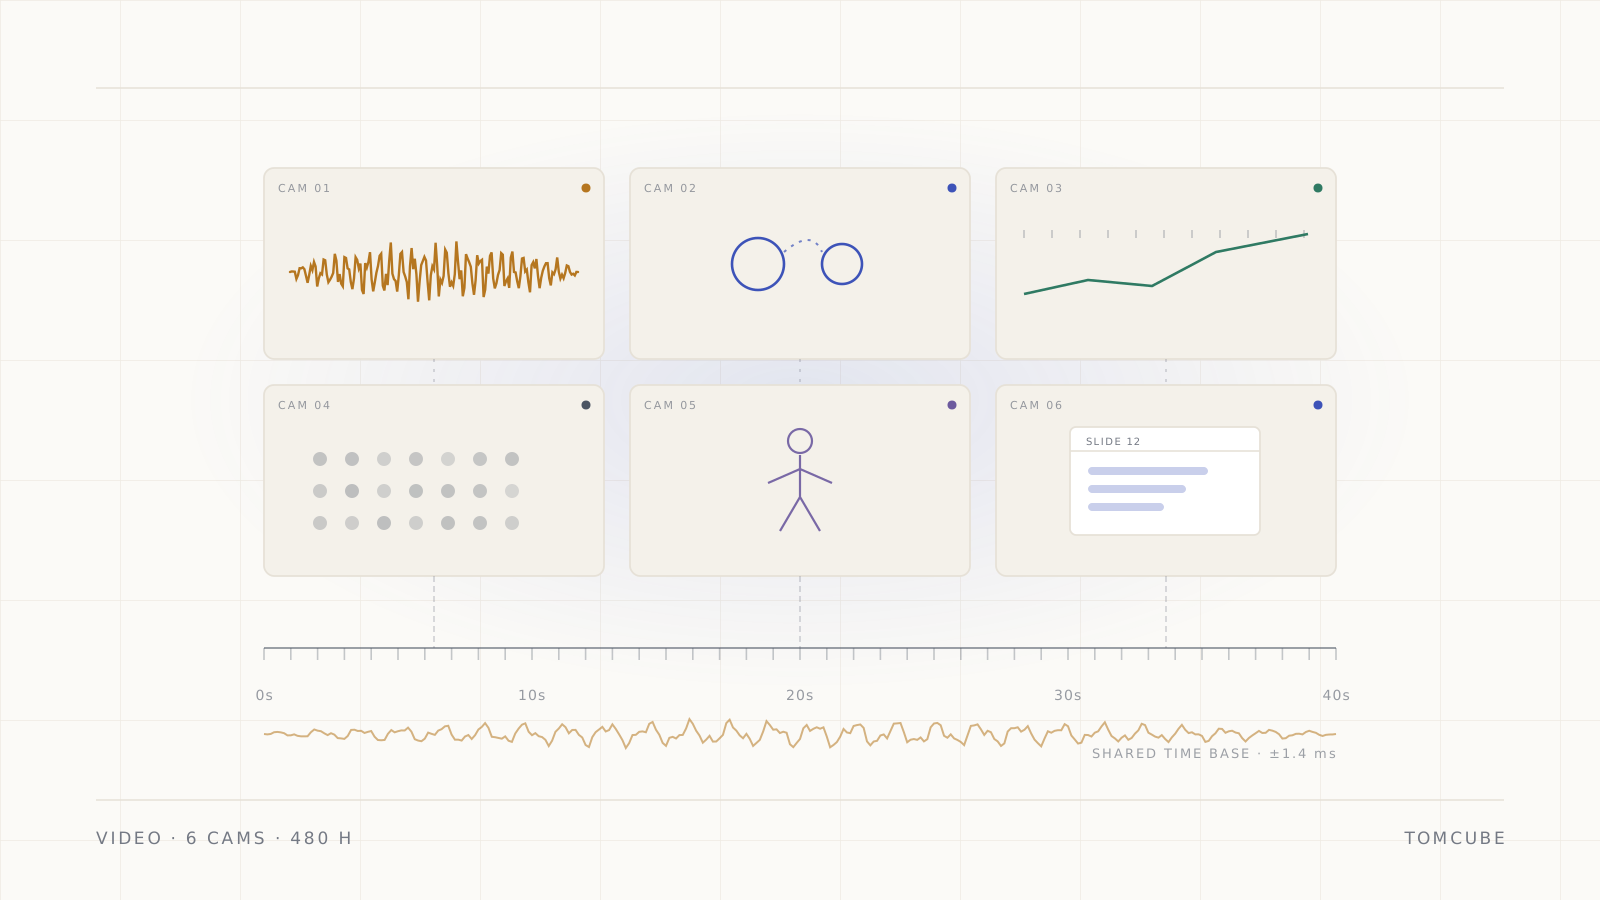
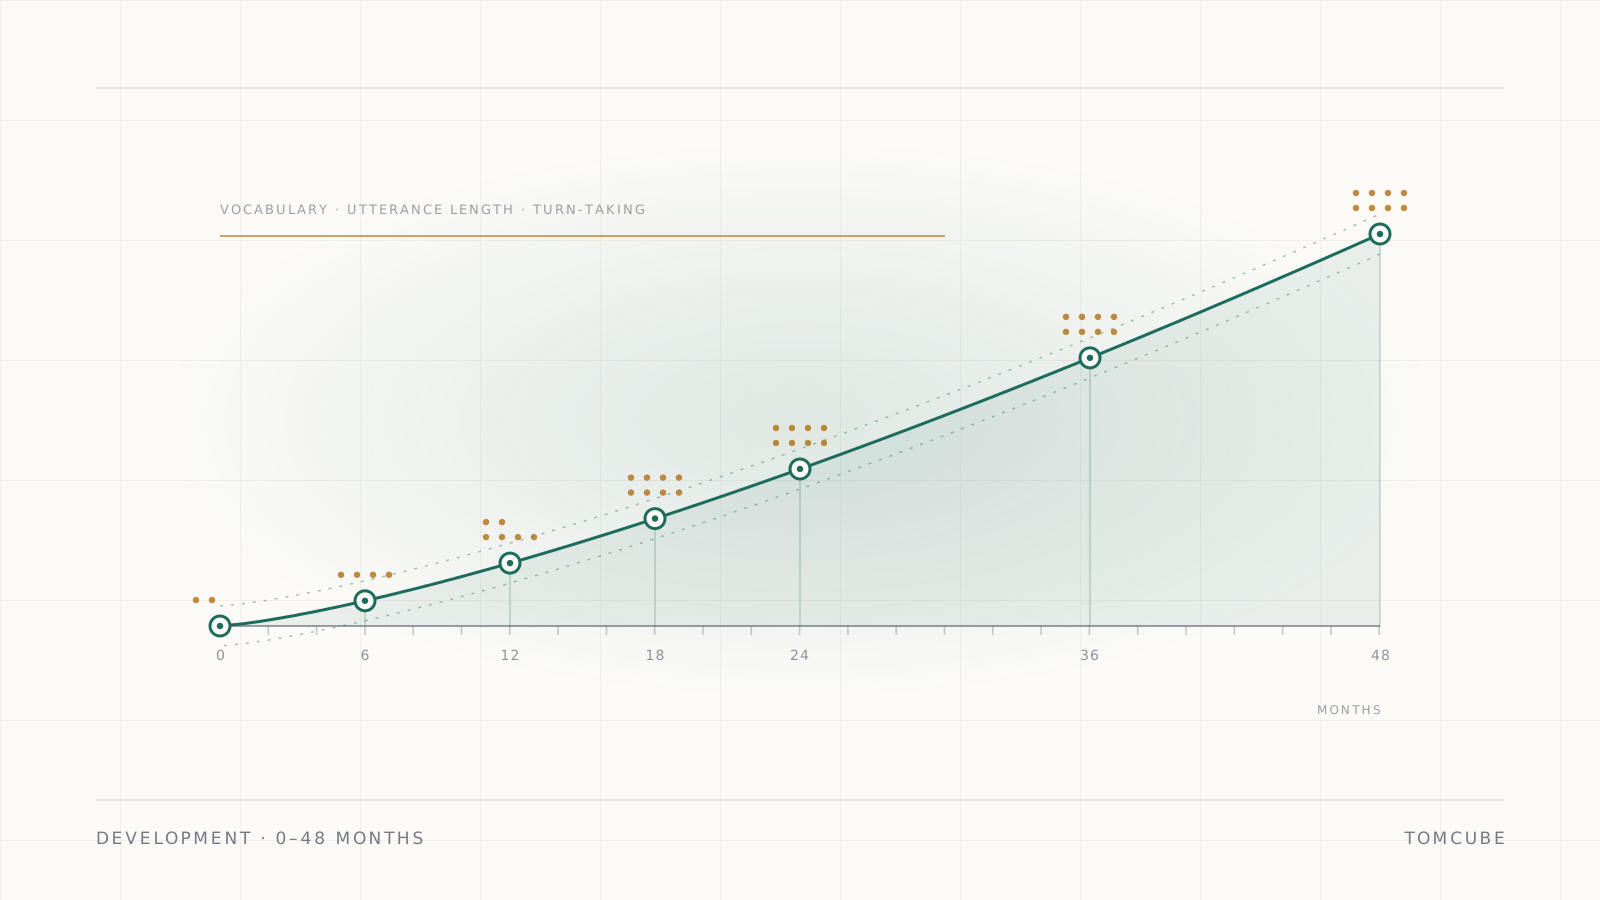
No datasets match this modality. Try another modality or view all entries.
03 / Validation
Every batch passes five validation gates
Validation is not a single spot check before delivery; it is a continuous process running through collection, processing, annotation and hand-off. Every batch keeps a traceable record.
- 01SYNC
Sync verification
Measure time offsets between audio, video, eye tracking, physiology and motion on a shared time base; a batch only advances when the median is within 1.4 ms.
- 02CONTENT
Content review
Spot-check transcripts, annotations and metadata per batch for field completeness, speaker matching and semantic consistency.
- 03KAPPA
Agreement assessment
Run double-blind review on key annotation layers and compute κ; below threshold, annotators are retrained and the batch is re-annotated.
- 04AUDIT
Reproducibility audit
Record devices, parameters, scripts and versions so anyone can reproduce the reported metrics from the audit checklist.
- 05ETHICS
Ethics & licensing
Informed consent, de-identification and licensing chains are documented item by item and tiered by research or commercial scenario.
DATA REQUEST
Need a dataset matched to your research question?
Tell us the research question, variable design and delivery date. We will come back with a subset plan, sample size and budget frame.
Reply within one business day · NDA and data licensing supported · Dedicated academic track