Multimodal language science · data infrastructure
Verifiable multimodal data for frontier science
We design, collect, process and verify multimodal data for universities, research institutes and enterprises. Speech, video, text and other signals are synchronized across time, space and position, then delivered as research-grade data that is reproducible, auditable and citable.
- ISO 27001 information security
- IRB ethics collaboration
- Used by 10+ institutions
00:12.480 Okay, let us put this chart on the group table, and then—
aligned1.4 ms
Cross-stream sync
κ 0.91
Agreement
98.7%
Batch pass
- 12,400hours
- Verified multimodal corpus
- 38languages
- Languages & dialects
- 10+institutions
- Universities & institutions
- 0.91κ
- Median annotator agreement
Net hours delivered after sync check and QA
Seven Mandarin dialect areas plus 12 minority languages
Linguistics, psychology, education and AI labs
Double-blind review, 2025 delivery batches
01 / Data modalities
Six modalities, one timeline
Single-modality data cannot answer multimodal questions. We align speech, video, text, eye tracking, physiology and motion on one time base, and deliver them under one verification standard.
Speech9 datasets
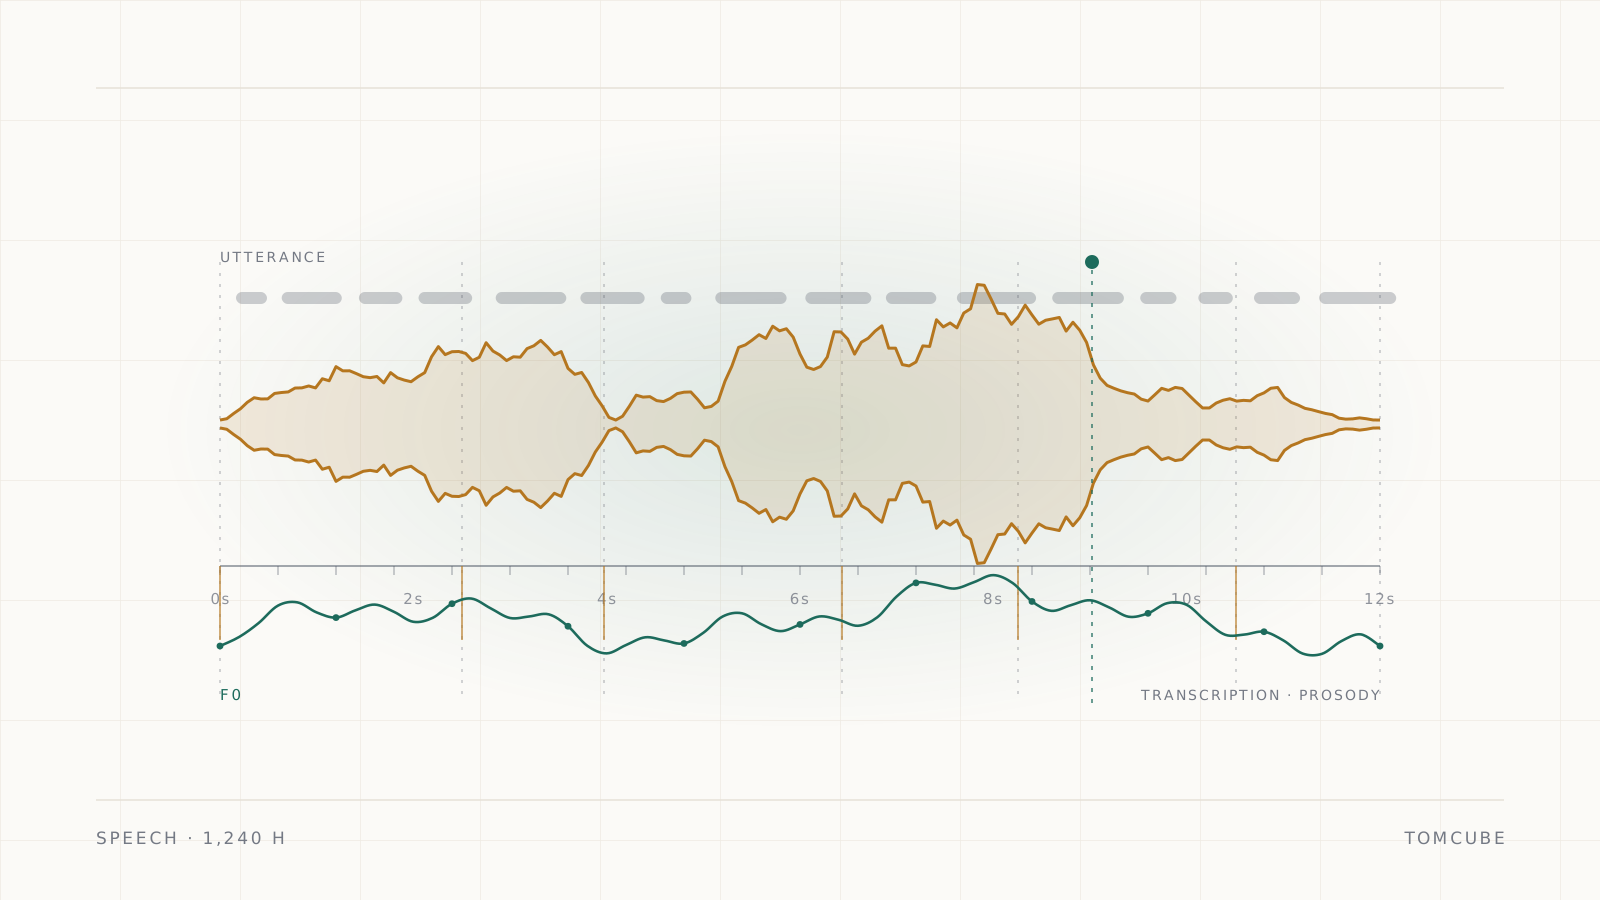
From close-mic lab recordings to far-field speech in real settings, covering read speech, conversation and multi-party interaction, with phoneme-level transcription and paralinguistic annotation.
Video6 datasets
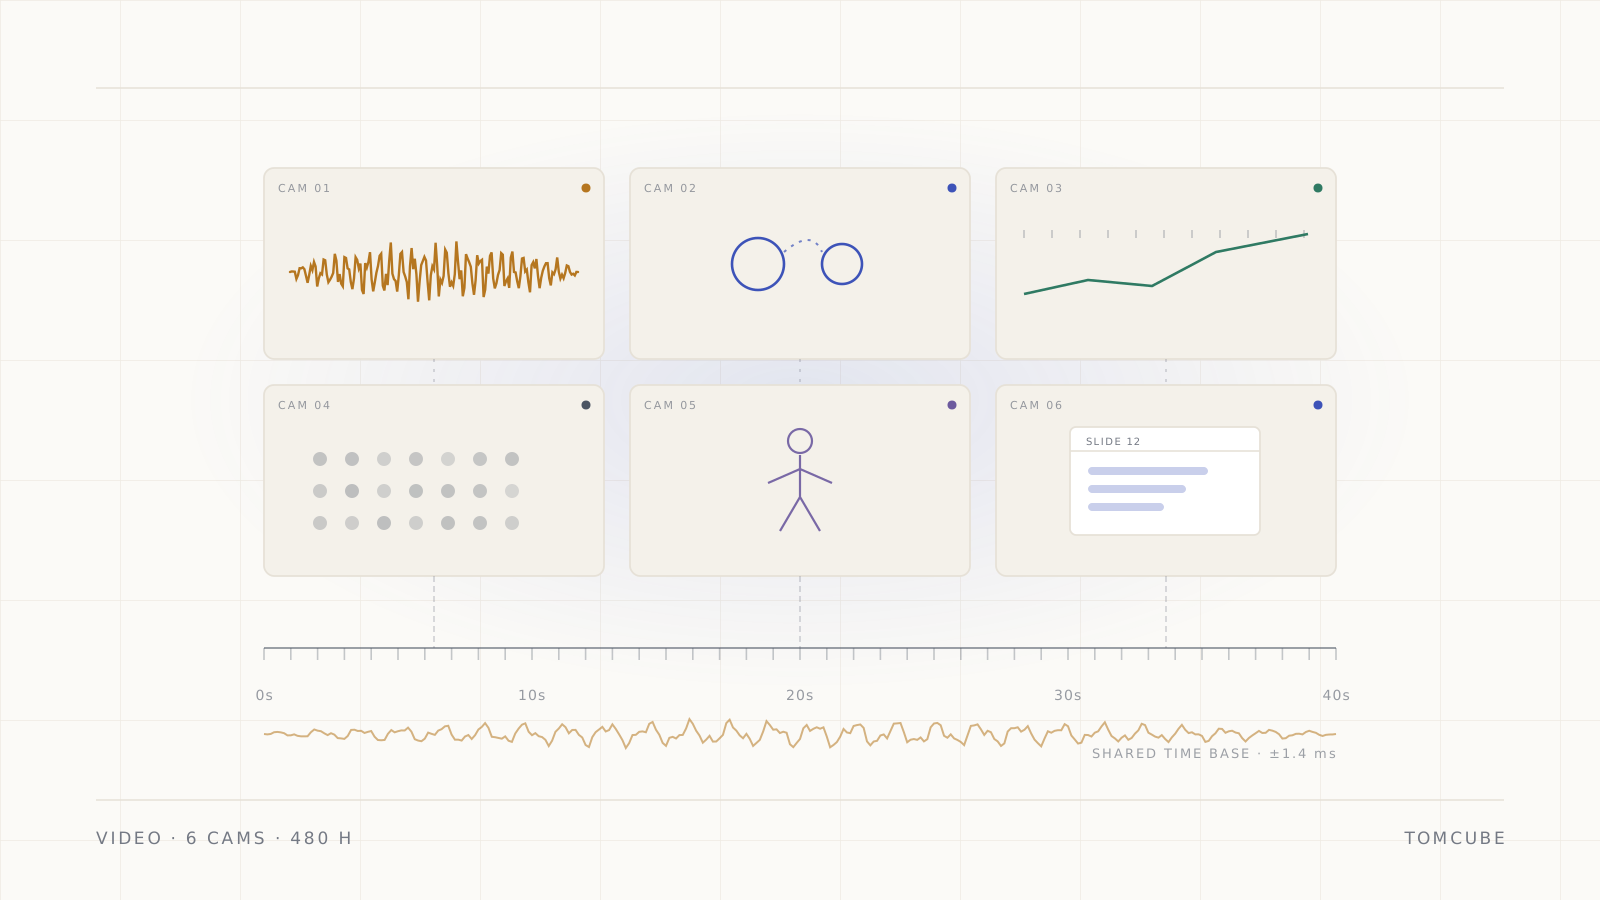
Multi-camera, wearable and screen recordings share one frame rate and time base, supporting frame-by-frame behavior coding, pose tracking and object-interaction annotation.
Text8 datasets
Verbatim transcripts, discourse structure and classroom talk codes aligned precisely with audio and video, ready for computational linguistics research.
Eye tracking & vision1 dataset
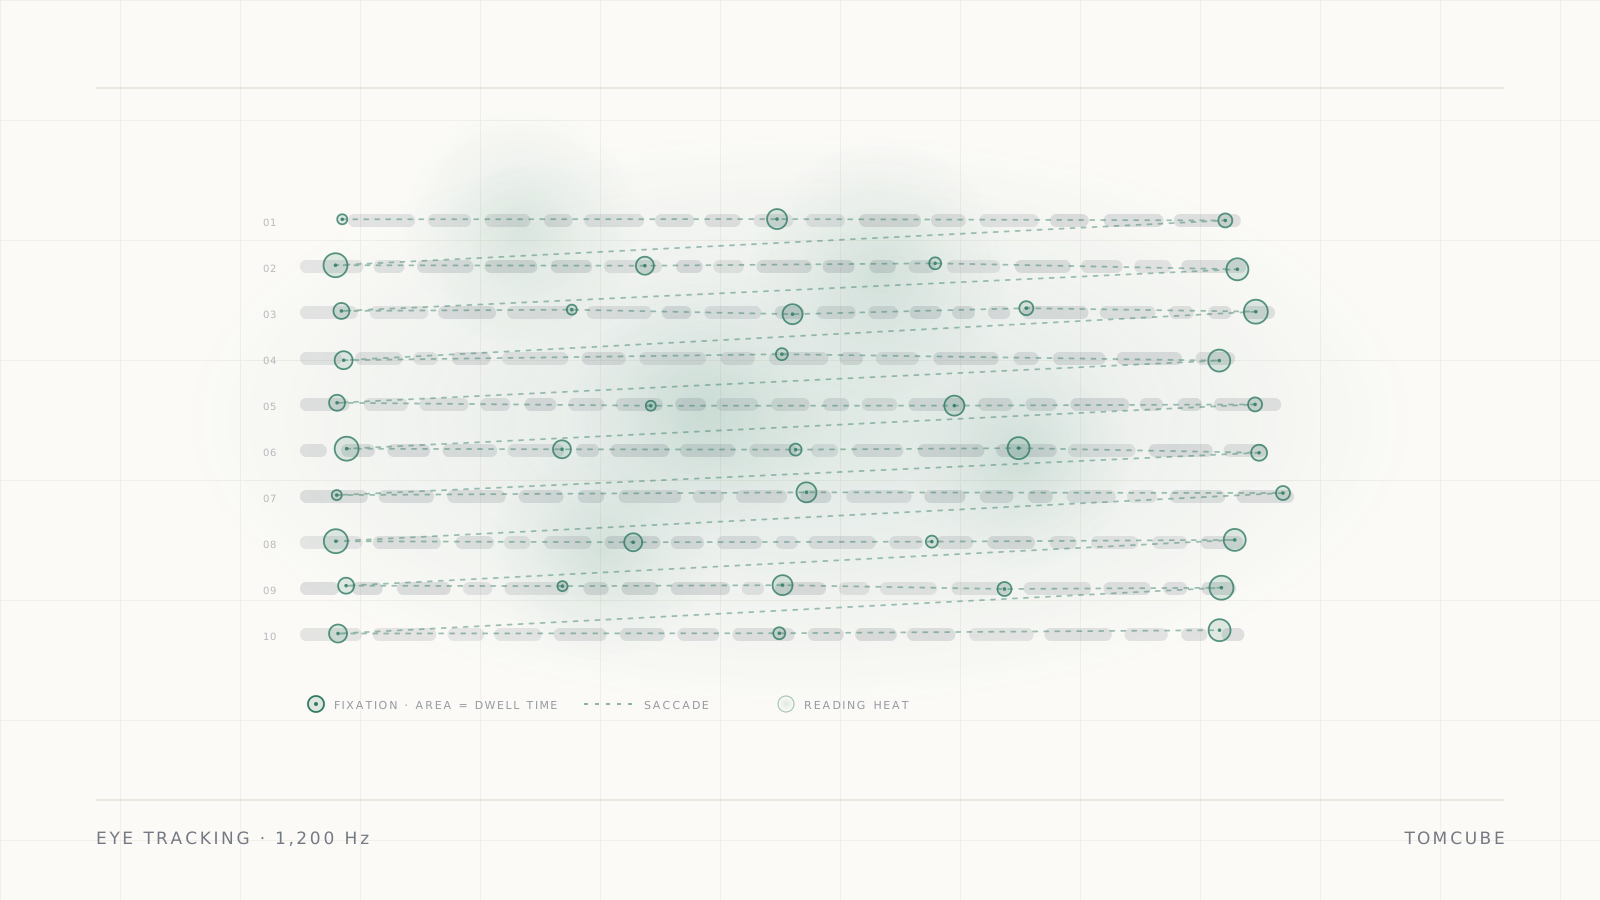
Screen-based and scene eye tracking with fixations and regressions aligned frame by frame to stimulus materials, supporting reading, attention and cognitive-load analysis.
Physiological signals2 datasets
EEG, EDA, heart rate and respiration carry hardware timestamps in the same clock domain, so they can be aligned precisely with language stimuli.
Motion & interaction1 dataset
Human pose, gesture and object-manipulation trajectories for behavior analysis, embodied AI and multimodal interaction research.
Cross-modal fusion
Streams are fused into unified episode files with sync manifests, annotation schemas and QC reports, delivered as RLDS, ELAN, JSON and other formats.
02 / How it works
From research question to verifiable data
It does not end when the recording stops. Every stage has explicit inputs, deliverables and acceptance criteria, and research teams can review progress and QC records at any time.
- 01Design
Study design
We define variables, codebooks, statistical plans and sample size with the research team, confirming up front what the data can and cannot answer.
- 02Collect
Collection
Devices and synchronization are configured per scenario; participant recruitment, informed consent and on-site QC are completed with a full collection log.
- 03Process
Processing & annotation
Transcription, forced alignment, segmentation and multi-stream fusion; annotation schemes are trained and double-blind reviewed to produce structured metadata.
- 04Validate
Verification & delivery
Only after sync checks, content review, agreement assessment and reproducibility audit pass does data enter the delivery manifest and licensing workflow.
Typical timeline: first verified batch delivered 4–6 weeks after scope sign-off · staged delivery and mid-course adjustments supported
03 / Datasets
Research-grade data, ready to request
Covering language development, classroom teaching, clinical communication, dialect preservation and human-computer interaction, every dataset ships with full collection documentation and a verification report.
04 / Verification
Verification turns data into evidence
The end of sampling is not usable data. Every batch must pass sync validation, content review, agreement assessment and a reproducibility audit before it enters the delivery manifest.
Sync validation
Frame-by-frame comparison of audio, video, eye tracking and physiological time bases, reported as an error distribution.
Content review
Transcripts and annotations are sampled and re-checked by a second reviewer; any batch above the error threshold is redone in full.
Agreement assessment
Double-blind annotation with κ / α coefficients reported as citable reliability metrics.
Reproducibility audit
Collection logs, device parameters, annotation manuals and version numbers are delivered so third parties can reproduce the results.
- Cross-stream sync error (median)
- 1.4 msthreshold 5 ms
- Annotator agreement
- κ 0.91double-blind review
- Batch sampling rate
- 20%manual review
- Batch QA pass rate
- 98.7%FY2025
Deliverables: qc-report.pdf · manifest.json · audit.log · annotation-spec v2.4
05 / Solutions
Two client types, six scenarios
Universities and research institutes care about publishable, reproducible results; enterprises and institutions care about data that feeds directly into models and products. One research-grade process serves both.
Universities and research institutes
Linguistics / psychology / education / medicine
Reproducible multimodal data and verification reports for grant proposals, publications and corpus building, covering experiment design, collection, annotation and quality assurance.
- Citable data description and methods material
- Ethics review and data management plan support
AI companies
Speech / multimodal foundation models / evaluation teams
Long-tail scenario corpora, reproducible evaluation sets and clearly licensed delivery for speech recognition, speech synthesis and multimodal foundation model teams.
- Reproducible evaluation sets with version numbers and source lists
- Long-tail coverage reports and baseline results
Healthcare and mental health
Hospitals / rehabilitation / psychology practices
De-identified multimodal corpora and compliant delivery for consultation communication, rehabilitation assessment and psychological measurement, balancing clinical usability with privacy requirements.
- Multimodal corpora with de-identification and licensing records
- Timeline annotation aligned with clinical scales
Education and publishing
Schools / teaching research / edtech
Multimodal classroom corpora, learning-outcome data and reusable evaluation tasks for classroom teaching, language learning and textbook publishing.
- Classroom multimodal corpora with teaching behavior coding
- Linked data on learning outcomes and classroom interaction
Smart cabins and in-vehicle voice
Automakers / Tier 1 suppliers / voice vendors
Multi-talker, high-noise, multi-zone speech and behavior data from real roads and simulated cabins, supporting in-cabin voice interaction and driver-state research.
- Synchronized multi-zone speech corpora inside and outside the cabin
- Cabin evaluation sets segmented by environmental condition
Human-computer interaction and product research
Product / UX / research teams
Put voice interaction, gaze, interaction logs and facial expression on one timeline, producing quantifiable, reproducible behavioral evidence for product decisions.
- Multimodal interaction logs on an aligned timeline
- Usability metric tables and an issue list ranked by severity
06 / Ecosystem
From university labs to industry settings
We work with different kinds of labs and research teams, keeping collection and verification methods grounded in real research settings.
- C9 university speech labsSpeech capture · prosody & speech technology
- Language university multimodal labsClassroom & interview · multimodal annotation
- Immersive audio perception labsSpatial audio · perception experiments
- Automotive intelligent multimodalIn-cabin multi-talker · noisy scenes
- Music conservatory multimodal labsPerformance motion · audio & physiology
- Language science & neuroscienceEEG / ERP · language processing
And many more collaborations across language science, cognitive science and multimodal interaction
07 / Research
Open methods, checkable results
We publish collection protocols, annotation guidelines and synchronization benchmarks as citable research outputs, and welcome research teams to build on them.
- Benchmark2026 · TOMCUBE Research
MC-Sync: A Synchronization Quality Benchmark for Multimodal Corpora
A reproducible protocol that measures audio, video and sensor synchronization error across six capture chains, based on 12,480 measured frames.
- Benchmark2025 · TOMCUBE Research
Dialect Speech Recognition Robustness Benchmark
Word error rate across 12 dialect sites and three noise conditions, with practical guidance on capture-side robustness.
- Protocol2025 · TOMCUBE Research
Classroom Multimodal Annotation Protocol v2
A layered annotation protocol for classroom corpora, from discourse acts and gesture to teaching events, with tag sets, boundary rules and double-blind review.
Sample pack v2.4
See the data before you commit
40 episodes, 8 synchronized streams and 4 real collection environments, with the full annotation schema and QC report.
- 40
- episodes
- 8
- synchronized streams
- 4
- real environments
- 2.4 GB
- package
Free to request · No NDA required · Delivered within one business day
Start a project
Tell us what you want to answer
Whether it is a grant application, corpus construction or model evaluation, we first agree on the research question, then propose an executable data plan, timeline and budget frame.
Reply within one business day · NDA and data licensing supported · Dedicated academic track